About Sigma300(ADAU1452) Architecture
Hello all,
I've got a question on SigmaDSP's architecture.
On the data sheet p.22, there is a line just as below.
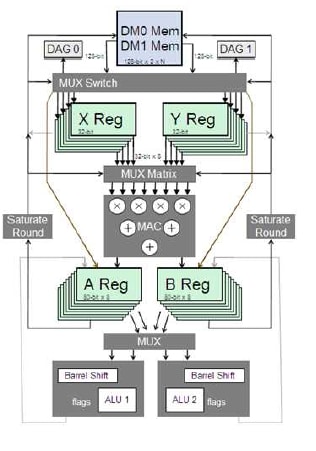
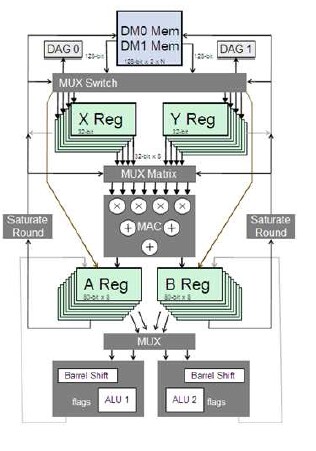
"By using a quadruple multiply accumulator (MAC) data path, the ADAU1452/ADAU1451 can execute more than 1.2 billion MAC operations per second"
I know that this speed is the theoretically fastest processing speed that the Sigma300 could possibly do.
But, could you please tell me how to accomplish it in detail?
Can this be accomplished only where there are MAC processing?
In case of "Dual MULT - Accum * Data - Double Precision"
The Functional Description says as below
Calculate the result of 2 accumulator register * data register as 8.56*8.24 in parallel.
This cannot calculate as 8.56*8.56?
Is there any limitation because of this?
Best Regards.
Hello Iron,
We really cannot provide any more detail on this. It is bordering on our protected IP. Why do you need to know this? We write all of our processing cells to use the core architecture to its most efficient extent.
Dave T
Hi Iron:
The number is NOT theoretical. For example our FIR filters and Biquad filters make use of this performance and Quad MAC feature.
The core can do a 8.24*8.48. In other words, we can do double precision times single precision (all in parallel). Most filter structures we use do not require the use of double precision coefficients since they don't contribute to quantization noise.
We can better guide you if you can share what you are trying to do. Can you please comment on the application and the need?
Thank you
Miguel
Hi Miguel-san,
I see. I understand that the number is not theoretical in case where FIR and IIR filters are used.
>Most filter structures we use do not require the use of double precision coefficients since they don't contribute to quantization noise.
=>I understand that most computing could be done by single precision on sigma.
My customer is trying to let the Sigma300 do 4 different kinds of audio processing simultaneously by the 4 MAC cores.
Is it possible?
Also my customer is pointing out how the barrel shifter works in the architecture.
When MAC processing, add operation is needed after multiplying.
At the time shift operation is also needed. However, the shifter is outside of the MAC block.
does this require you an additional cycle count?
Would like to know the computing flow.
Best Regards,
Yuta M
Hello Yuta,
It does not require an additional cycle.
I just need to inform you that we cannot continue answering these specific types of internal operations questions on the open forum. Please contact us and let us know who the customer is and we can continue the conversation off-forum directly with the customer.
Thanks,
Dave T
Hello Dave,
Thank you for your reply.
I understand that this topic should be done off-forum.
Could you tell me the contact of a person in charge please?
I am going to share the customer and detailed back ground of this conversation.
Best Regards,
Yuta M
The big question is, why would you consider the DSP's capabilities to be "protected IP", instead of publishing its architectural details and instruction set as is done with most DSP architectures (yours and that of your competitors).
Hello Matthijs,
A few reasons, first, because we came up with a very good architecture and want to keep the competition from copying it. Second is that users use the functional block in SigmaStudio and do not directly program the DSP. So there is no need to publish the instruction set and all the architectural details like in the other general purpose DSPs. The idea is to make development easy and quick. If we were to open up the part then we would have to double ( or triple) our support team to be able to support all the questions and problems that developers would have. This would defeat the entire purpose of making these parts easy to program, high performance and low cost.
Dave T
Please log in to reply.